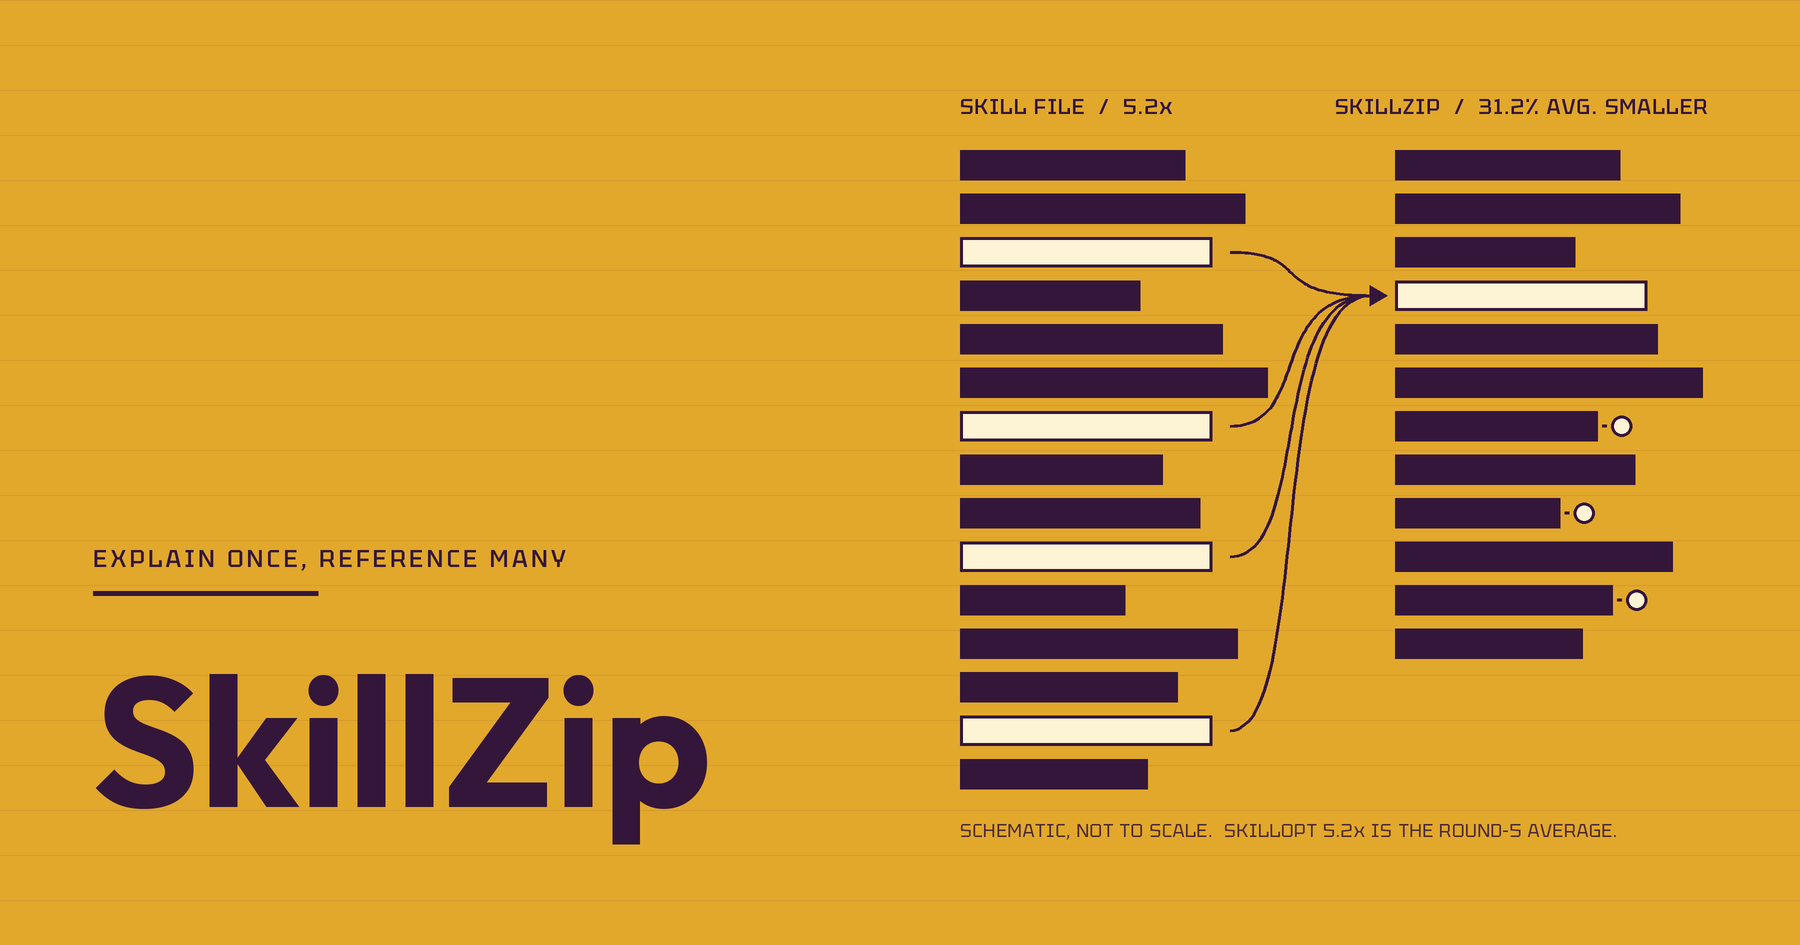
Self-evolving agents only ever append to their skill files. SkillZip merges the repetition with no task-based validation, shrinking them 31.2% on average, with caveats.
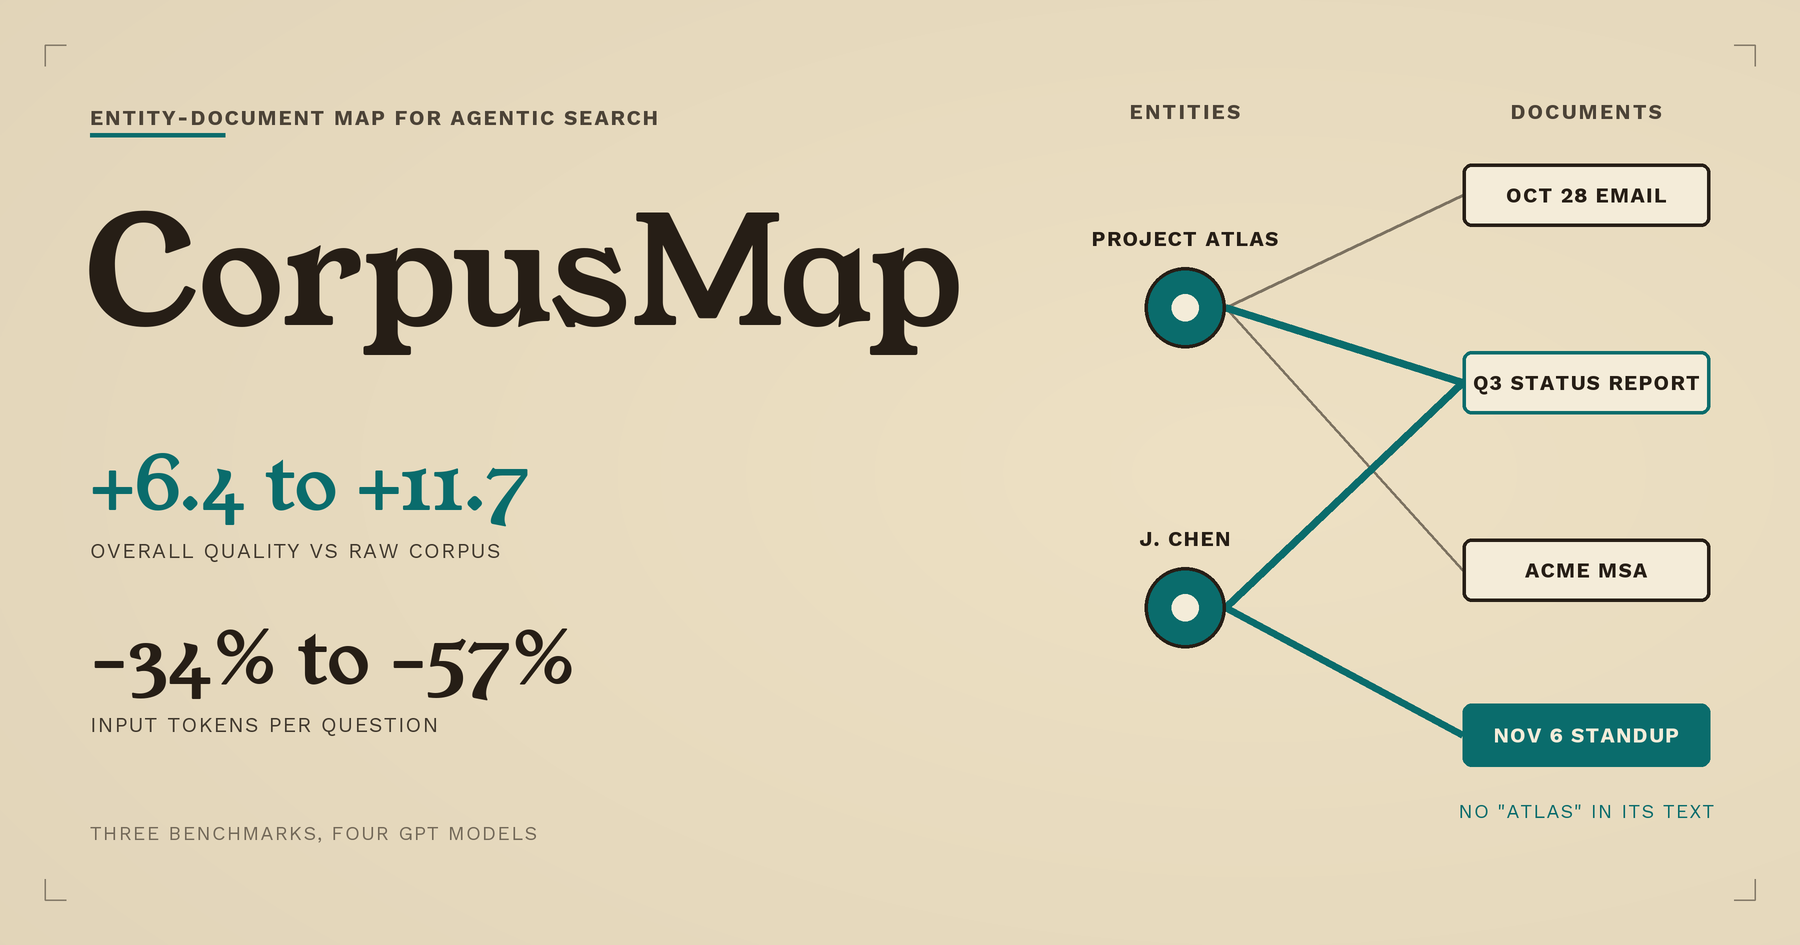
CorpusMap precomputes an entity-document map so search agents follow links, not rediscover them: +6.4 to 11.7 Overall Quality points and 34% to 57% fewer input tokens.
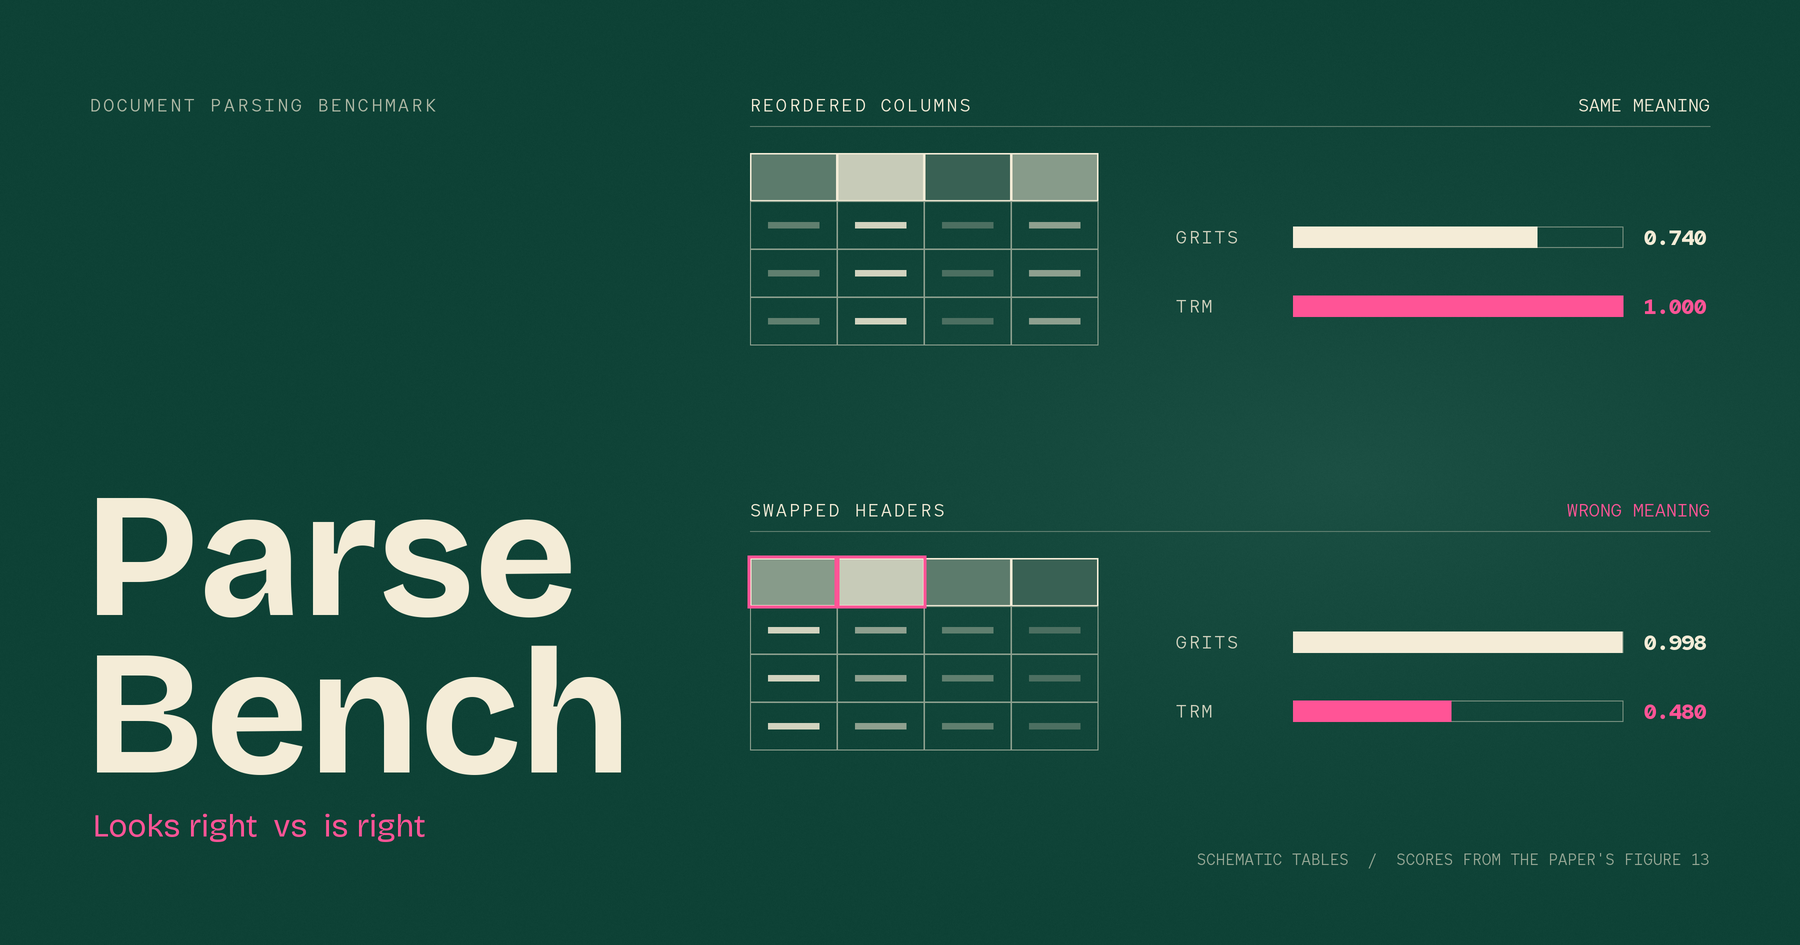
ParseBench scores PDF parsing by whether an AI agent can act on the output, not by text similarity. Its table metric is worth borrowing; the leaderboard needs a discount.
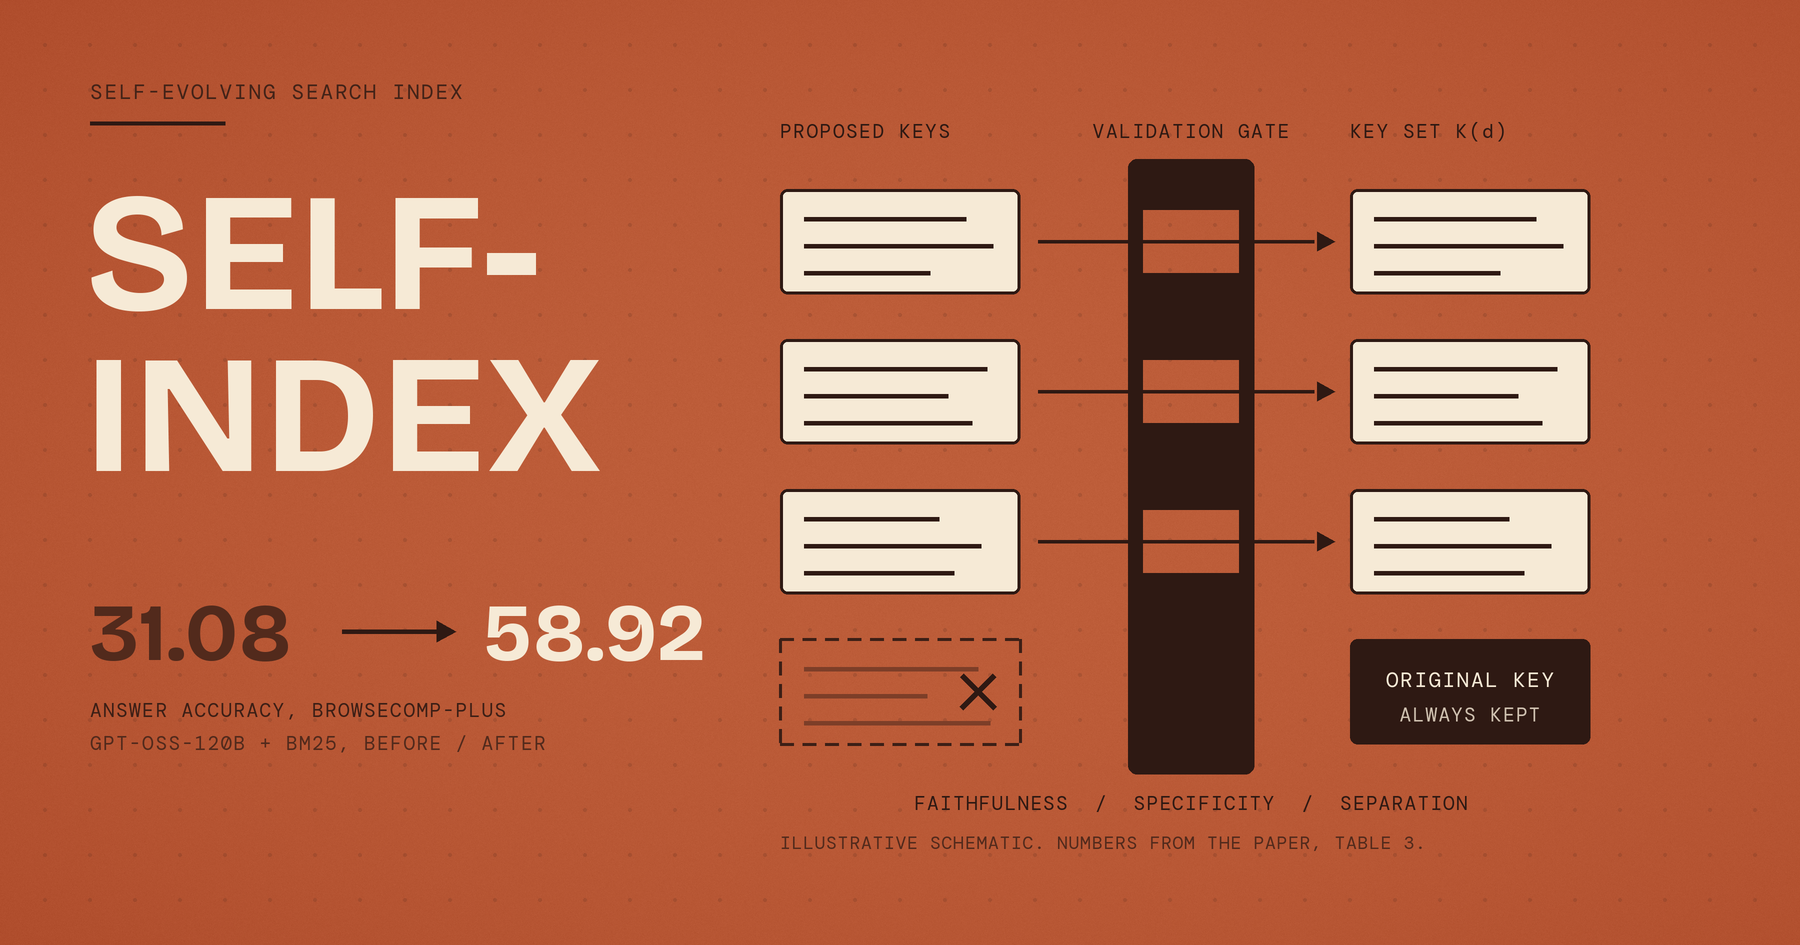
SELF-INDEX lets an LLM find weak search-index keys, revise only those, and apply a change only after validation. Strong engineering, but the judge is also the generator.
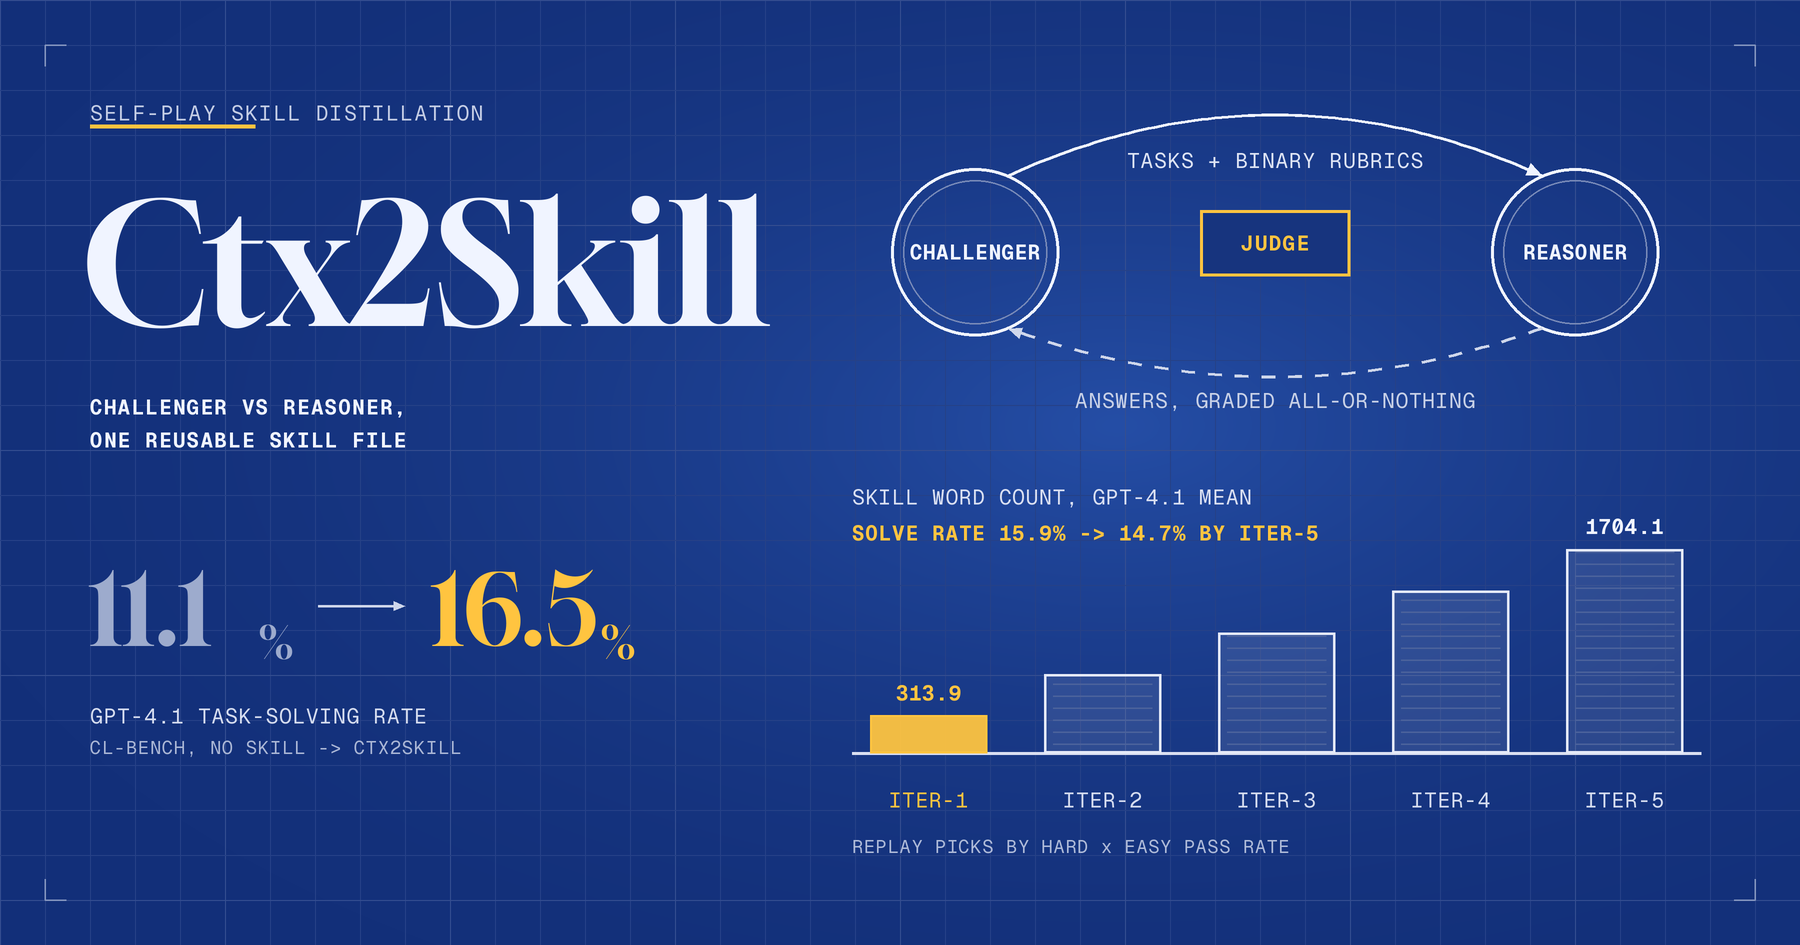
Ctx2Skill pits a Challenger against a Reasoner to distill a long text's hidden rules into a reusable skill file, no labels needed: GPT-4.1 rises from 11.1% to 16.5%.
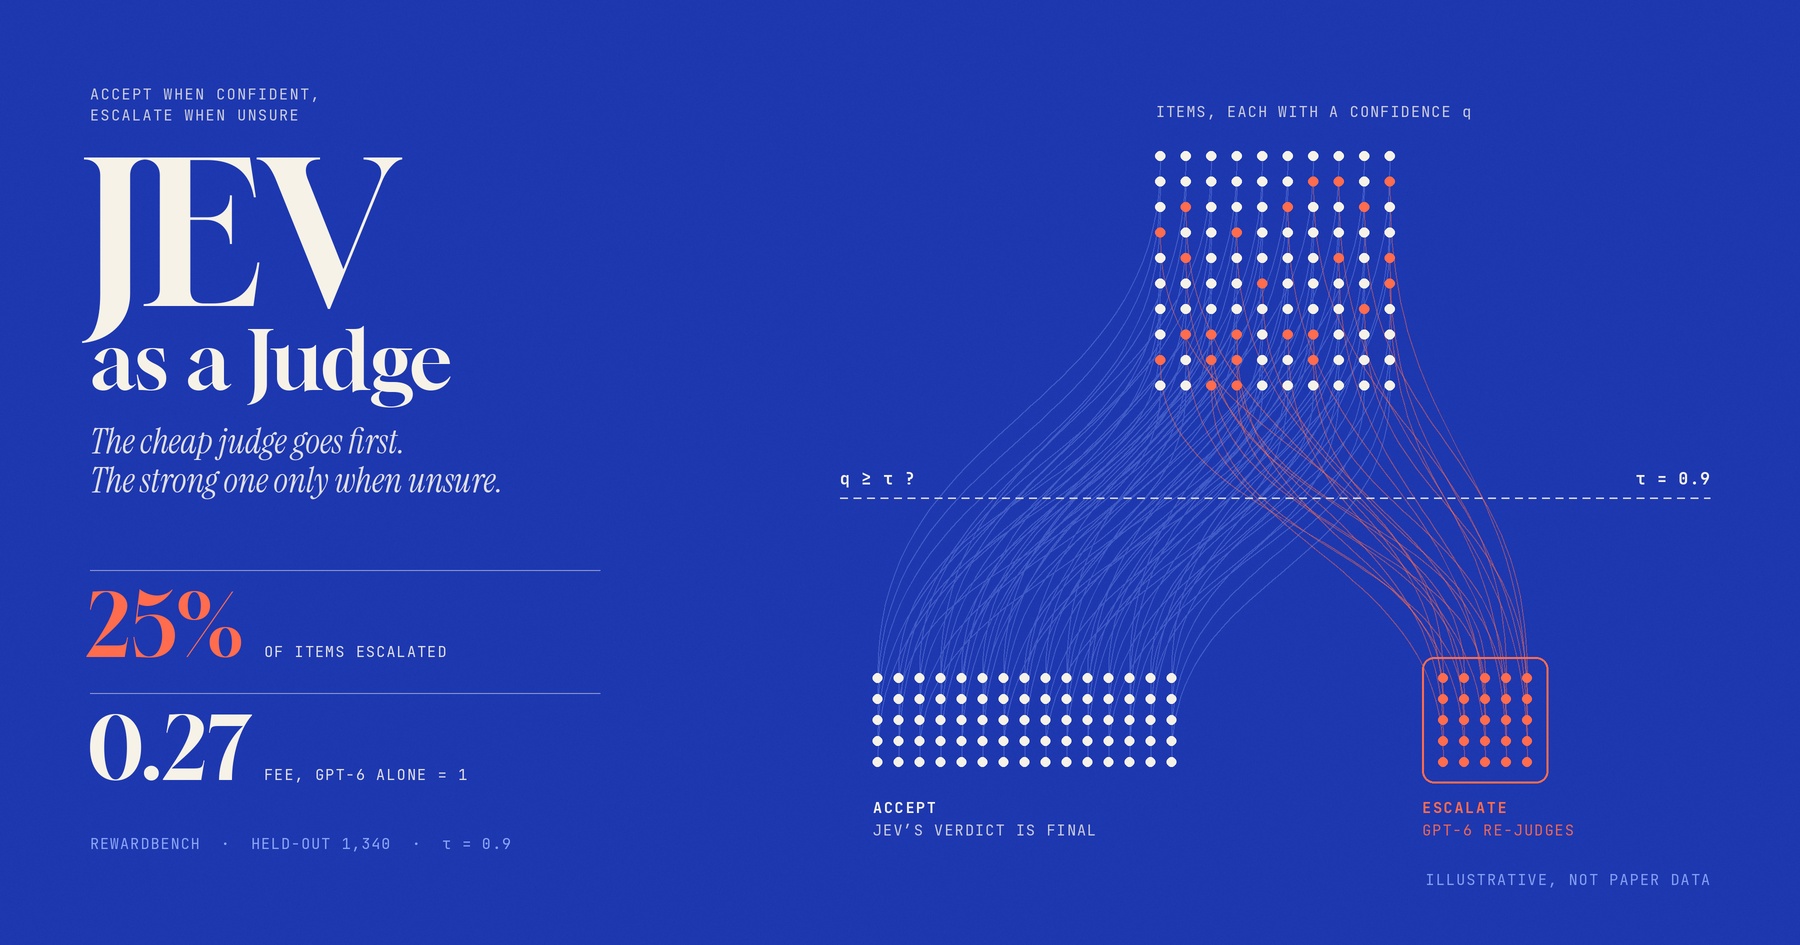
A third-party test of JEV, a cheap LLM judge that escalates unsure cases to GPT-6: 27% of the cost on easy tasks, only 9-33% saved on hard ones. AUROC explained.
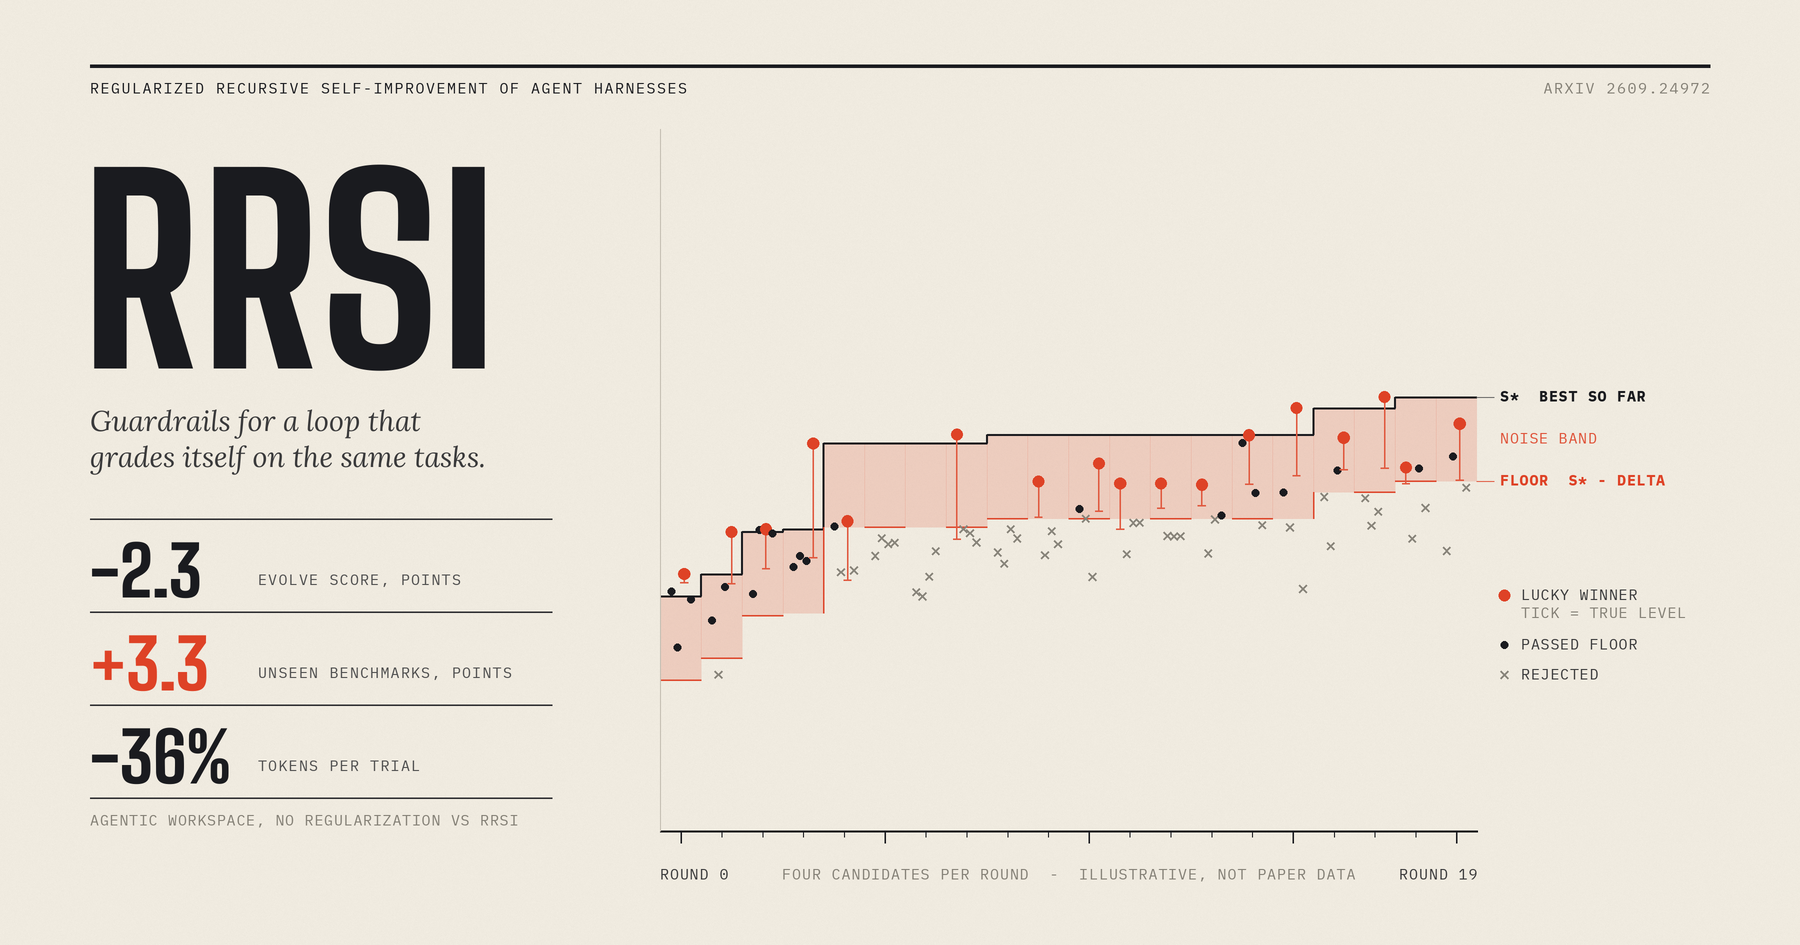
An agent that rewrites its own harness and is scored on the same tasks looks better every round, yet the gains may not transfer. Google's RRSI adds guardrails to curb it.